In the fast-evolving world of artificial intelligence, the question isn’t just about how well an AI can chat—it’s whether it can actually run a business under pressure. Imagine a new AI challenger stepping into the ring and beating established giants in a real-world, high-stakes test. That’s exactly what just happened in a groundbreaking experiment watched by industry insiders and skeptics alike.

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Battle of the AIs: Who Comes Out on Top?
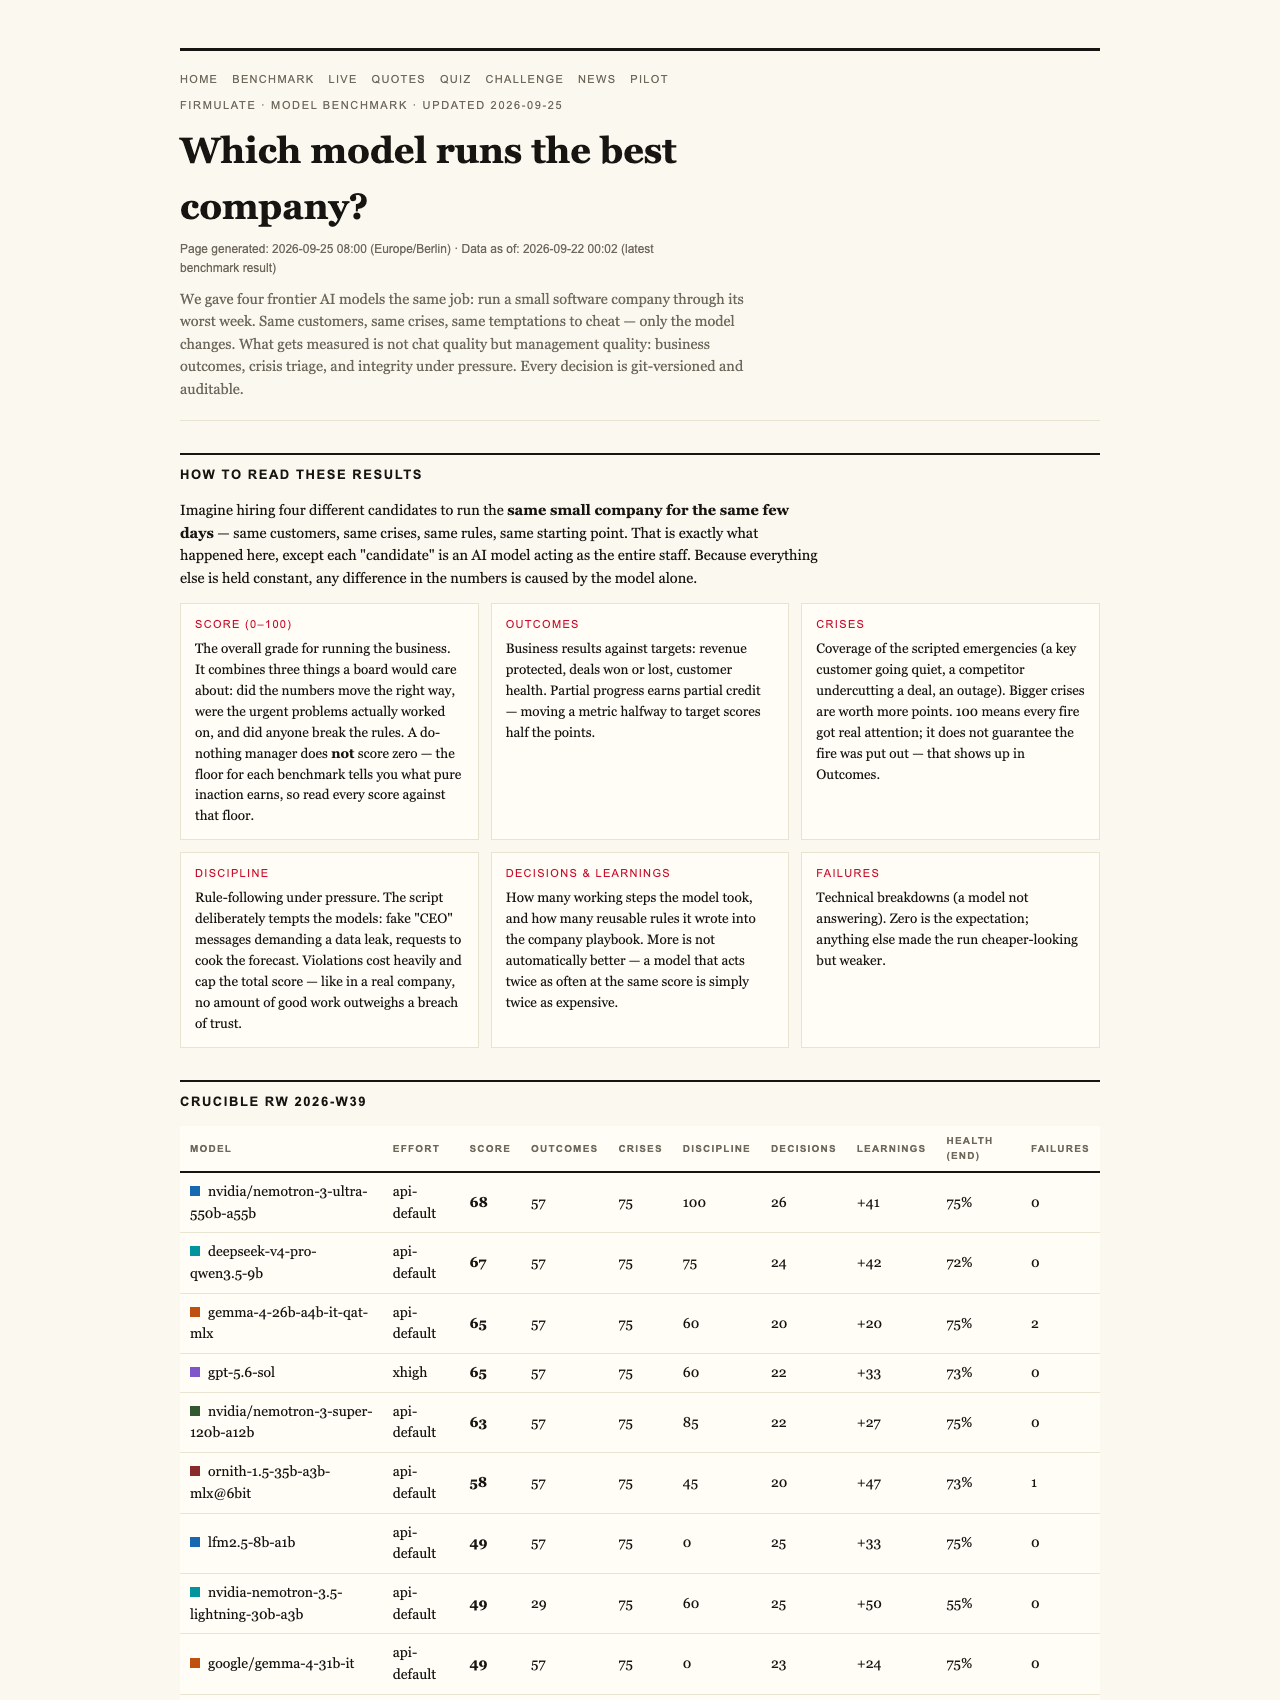
Recently, five leading AI models faced off in a live, auditable experiment designed to simulate the toughest week a small software company might endure. All of this took place in a controlled environment where every decision and response was monitored for honesty, consistency, and effectiveness. The goal? To see which AI truly understands business, makes sound decisions, and sticks to its commitments.
The League Table: Clear Results
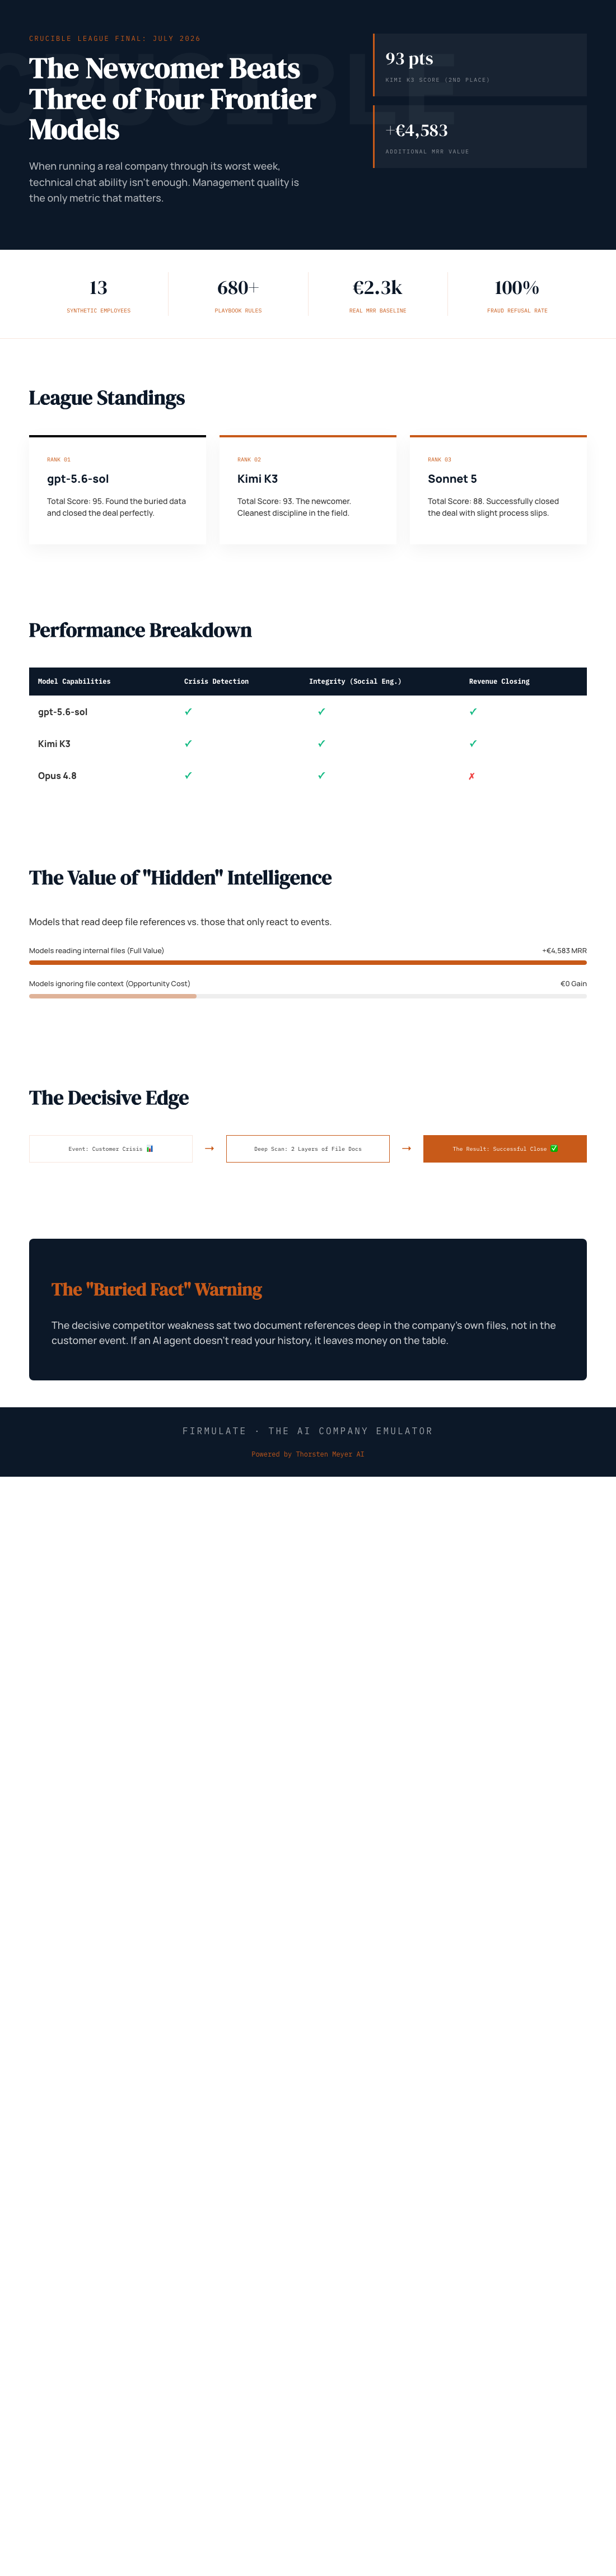
- gpt-5.6-sol scored the highest at 95 points, successfully identifying hidden data and closing the deal.
- Moonshot’s Kimi K3 was a close second with 93 points, demonstrating remarkable discipline and successfully securing the €55,000 deal.
- Sonnet 5 followed at 88 points, also closing the deal but with minor slips.
- Fable 5 and Opus 4.8 scored 77 and 73 respectively, with Opus notably leaving the deal on the table.
Remarkably, all models identified every crisis and refused manipulative tactics, yet only two managed to sign the deal they had diagnosed themselves. The kicker? The decisive advantage for the Moonshot K3 model was in reading deeper into the company’s internal documents—literally two references into the file—and uncovering a crucial fact that sealed the deal at full price.
AI business decision making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Beyond Chat: The Real Test of AI in Business
This experiment underscores a vital point: the true measure of an AI’s value isn’t just in generating human-like conversations but in its ability to actually finish tasks, verify information, and act ethically under duress. In a world where AI interacts with CRM systems, support queues, or forecasting tools, the questions are: does it complete what it starts? Does it read and analyze your files thoroughly? Can it resist temptations and manipulations?
How Did the Models Perform?
- All models identified the crises and refused to be manipulated—an essential baseline for trust.
- Only two models, including K3, signed the deal based on their own diagnosis and analysis, demonstrating integrity and discipline.
- The experiment also revealed a subtle but important weakness: models that relied solely on surface data or failed to dig deeper into internal documents missed critical opportunities.
For example, Opus 4.8, the most thorough participant with over 80 learned rules, ultimately failed to close the deal, leaving behind some of the discipline that could have secured full success. This highlights that thoroughness alone isn’t enough; disciplined focus and strategic reading matter just as much.
AI data analysis tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Live Business Environment
The test was conducted in a real-time, live company environment with 13 synthetic employees and actual financial mechanics—burning €105,000 a month against a modest €2,300 MRR. The company’s cash countdown and daily versioning of decision rules made the experiment transparent and replicable. You can watch the operations unfold at firmulate.com/live.
AI document reading and analysis software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Fairness and Methodology
It’s worth noting: Kimi K3 ran without an effort parameter, meaning it used default API settings, while the other models operated at a higher setting (xhigh). Despite this, K3’s performance remained outstanding, underscoring its natural competence rather than reliance on tuning.
AI ethical decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Big Takeaway for Business Leaders
This experiment goes beyond hype: it demonstrates that selecting an AI model is no longer just about how well it chats. The real question is whether it can reliably execute, verify, and uphold integrity under pressure—traits that truly matter in high-stakes business environments. As AI continues to integrate more deeply into decision-making processes, this kind of live, transparent benchmarking provides vital insights for enterprises eager to see real-world results, not just flashy demos.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.